

Open any AI engineer or Forward Deployed Engineer job post and you’ll see some version of the same line: “RAG experience on real enterprise data.”
That leaves most people stuck. How do you get enterprise experience without already working at an enterprise?
This week’s answer is a dataset I keep coming back to, plus the lab I built around it.
Meet TechQA
TechQA is a free dataset of real IBM technical support questions, asked by real IBM customers. It isn’t synthetic and it isn’t tidy Wikipedia trivia.

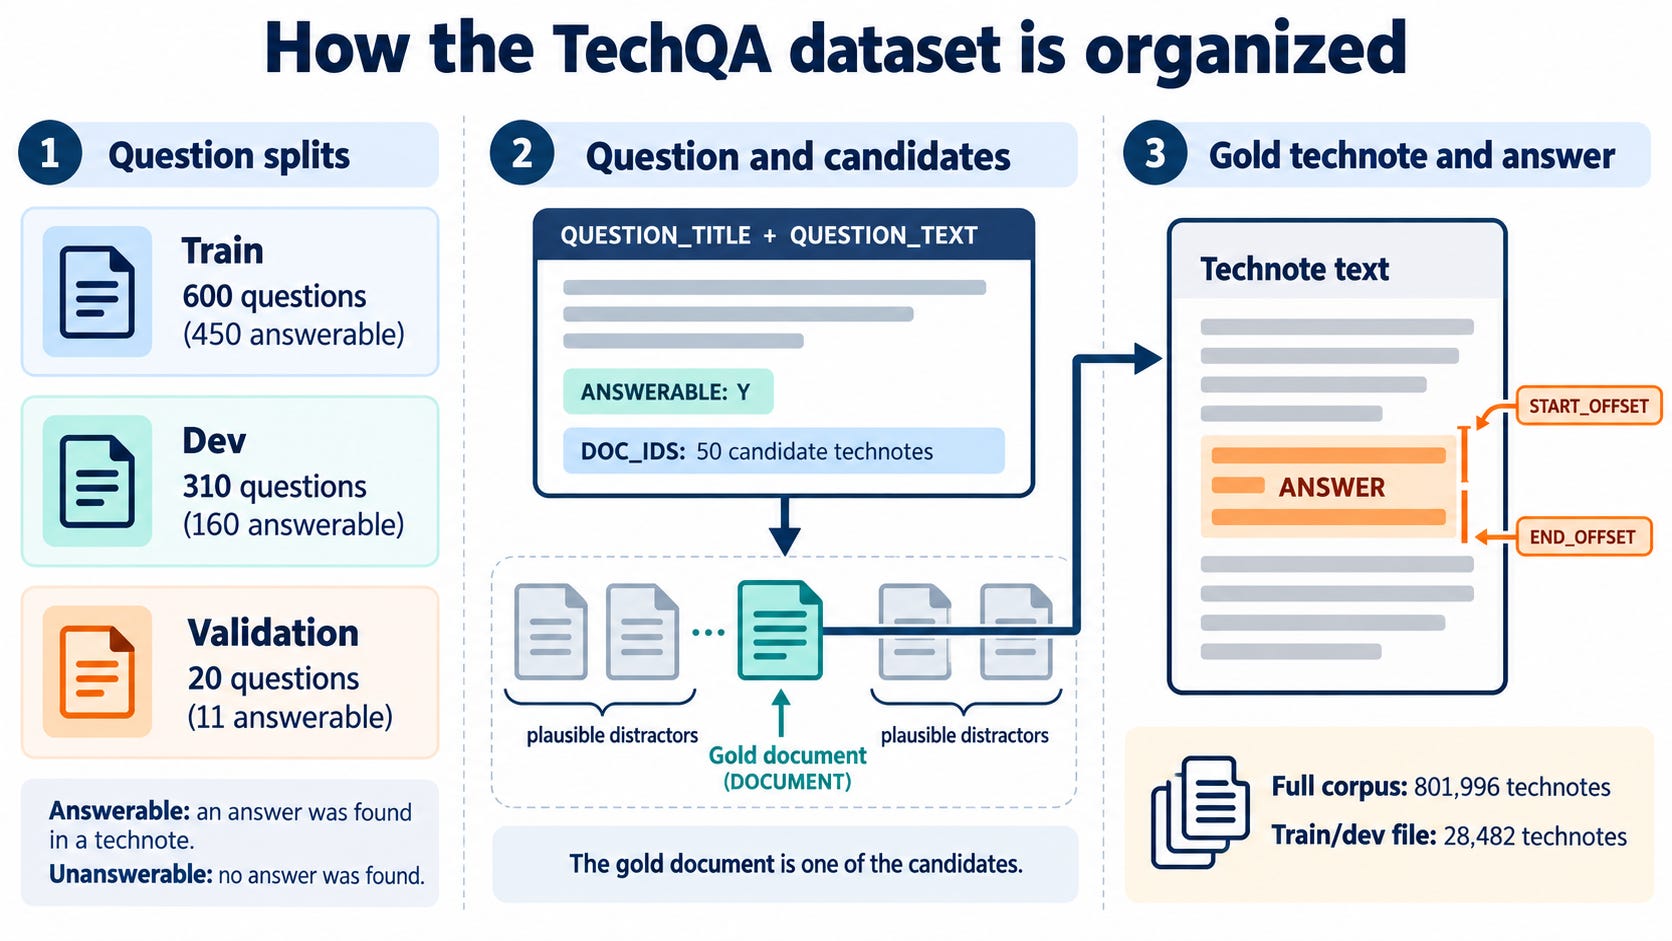
Every question comes with 50 candidate documents (IBM “technotes”):
One is the right page.
The other 49 are look-alikes: same product, same error codes, almost the same title.
And sometimes none of them are right.
That last point is the important one. It’s exactly what a client’s knowledge base looks like: messy pages that all sound the same, and questions where the honest answer is “I can’t find support for that.”
Learn to handle that and you’ve learned what clients actually pay for.
The lesson you can’t fake
Here’s what separates people who’ve built this from people who’ve watched videos about it.
TechQA tells you where each answer sits inside its source page (a start and end offset). So you can measure something most tutorials never check.
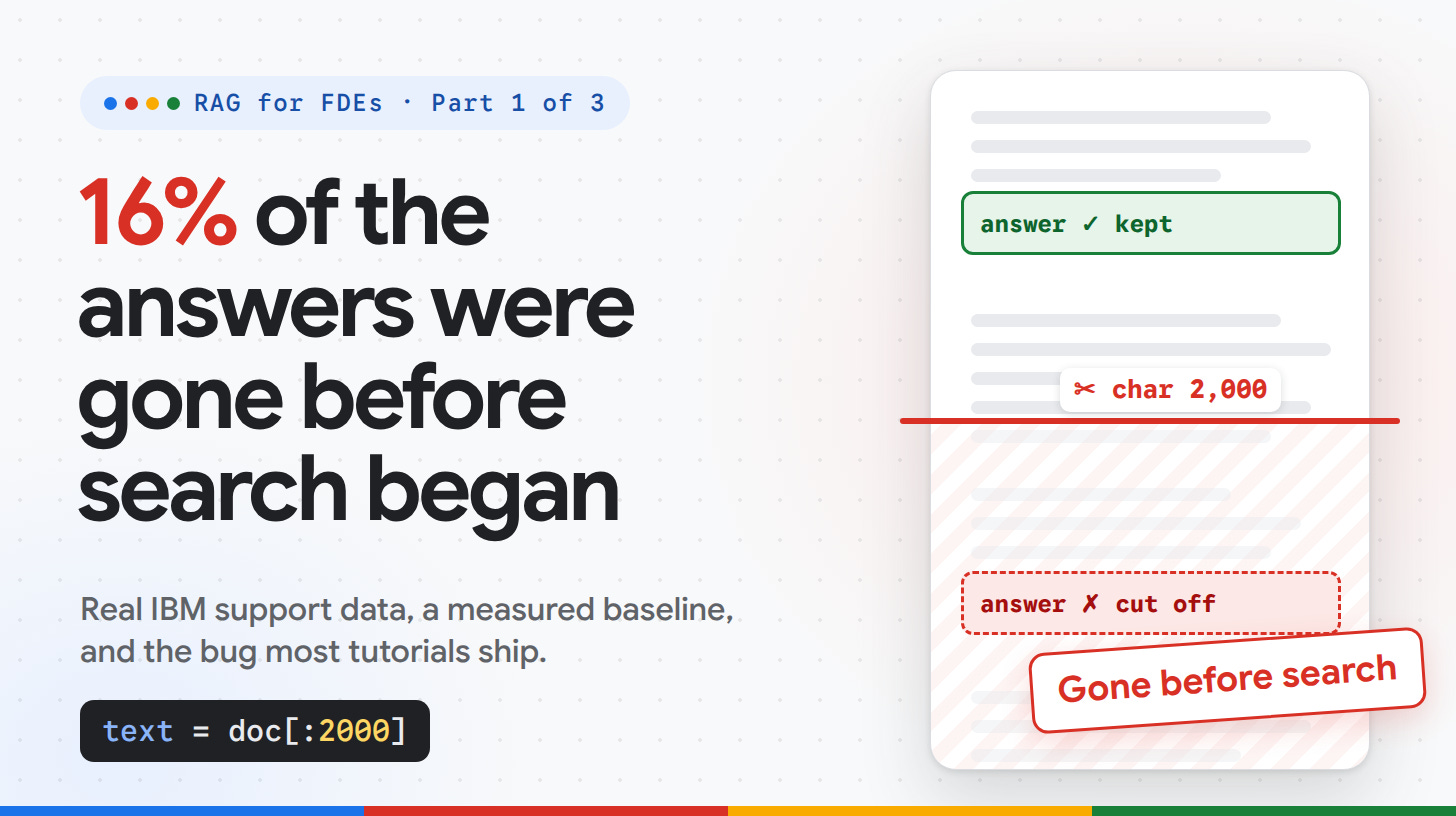
When I measured it, 16% of answers start after character 2,000.
Now look at what a lot of tutorials do:
text = doc[:2000] # “just keep the opening of each document”For that 16%, the answer is gone before search even begins. No retriever, re-ranker or prompt can recover text you’ve already thrown away.
You only learn this by measuring.
What you’ll build in the RAG Lab
The lab takes you from raw data to a measured baseline:
Inspect the data: splits, answerable vs. unanswerable questions, candidate lists.
Compare raw HTML with clean text: what does stripping actually change?
Measure answer positions: where do answers live, and what does truncation cost you?
Build a BM25 search: a simple, honest keyword baseline.
On 160 real questions, the BM25 baseline found:
the right page first 47% of the time
the right page in the top 5 63% of the time
That’s your number to beat. Even better, the failures tell you what to fix next: the query, the documents, or the ranking.
That’s the exact workflow you’d walk an interviewer through: data first, then measurement, then a baseline, then targeted fixes.
Real scale, on your laptop
You start with about 28,500 documents, then move to the full library of 802,000. That’s 28× bigger.
At that size you hit the problems you’d normally only meet on the job: indexing time, memory, and whether your results still hold up as the data grows.
Try this before next week
Even if you never open the lab, try this one exercise on whatever RAG project you have:
Find out where your answers live. For a handful of questions you know the answers to, record the character position of the answer in its source document. Then check whether your chunking or truncation keeps it.
If you find answers past your cut-off, you’ve just found a bug that no amount of prompt engineering will fix.
What’s next
This is Part 1 of a 3-part series on RAG for FDEs: retrieval, or finding the right source before you ask a model to answer.
You don’t need an enterprise job to build enterprise skills. You need the right dataset, honest measurement, and a system that knows when to say “I can’t find support for that.”
Hit reply and tell me your BM25 numbers (or where your answers ended up living). I read every reply.
See you in Part 2, Zahir The Adaptive Engineer