

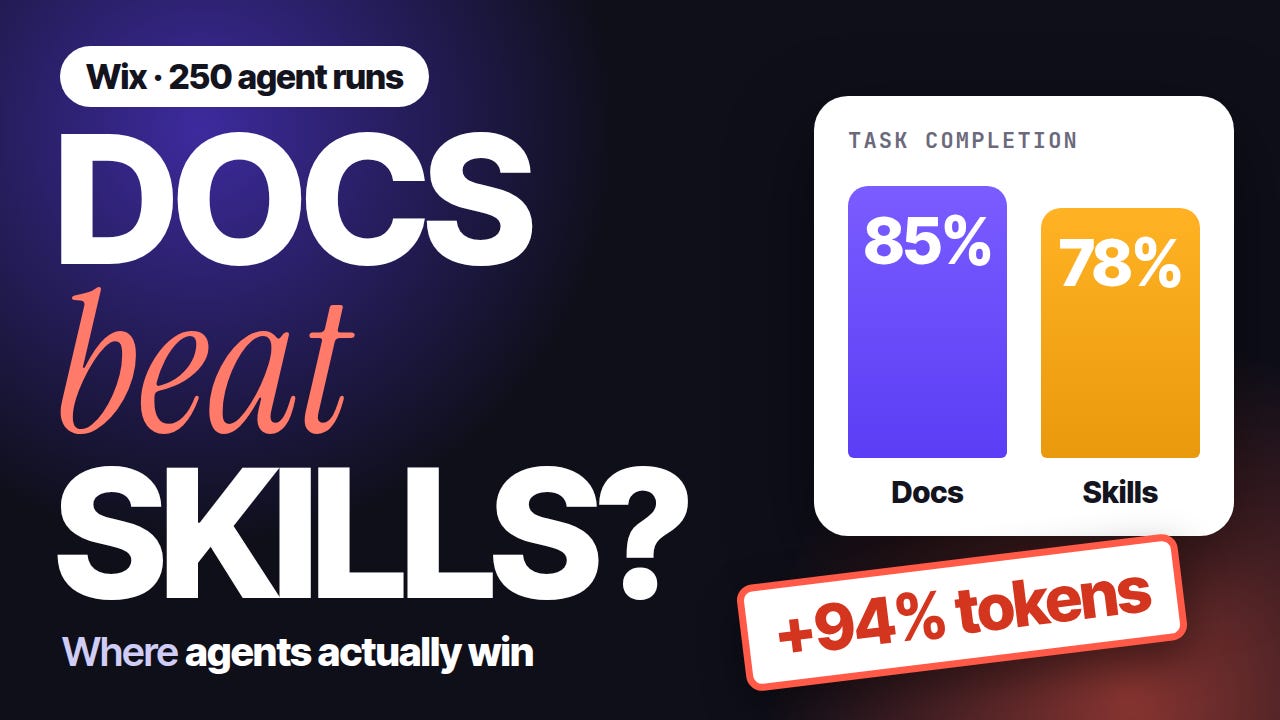
Everyone is writing skills for their AI agents. Wix asked the question almost nobody asks: are they actually better than the docs they came from? Then they ran 250 agent evals to find out.
What they found
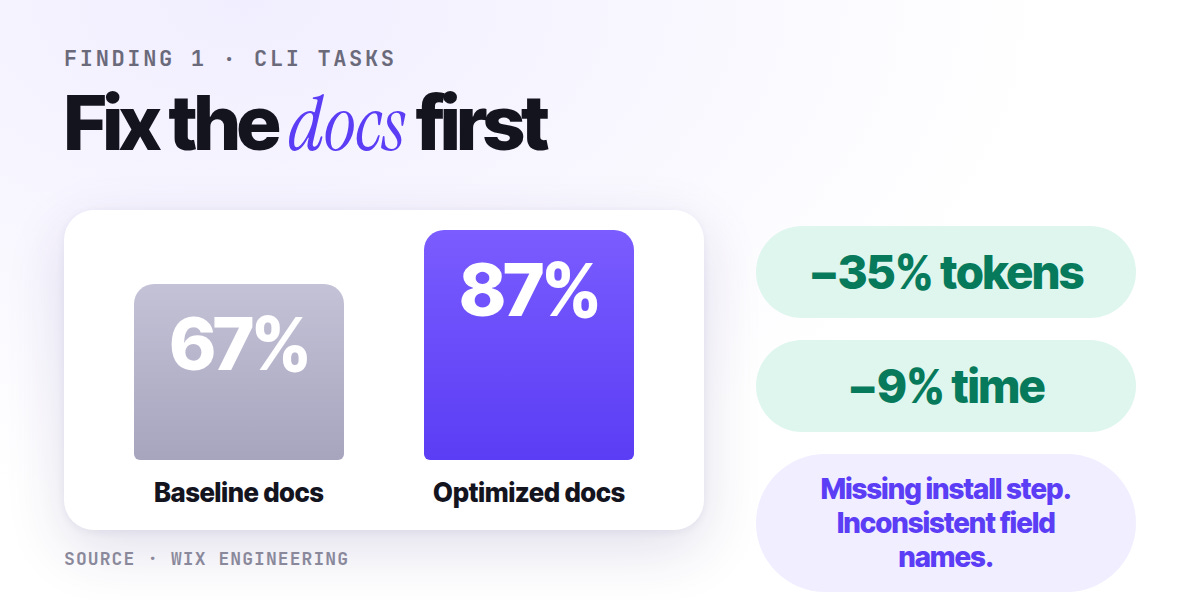
1. Fix your docs first. On CLI tasks, optimized docs took completion from 67% to 87% and cut tokens 35%. The fixes were boring: a missing method call, inconsistent field names, an undocumented install step.
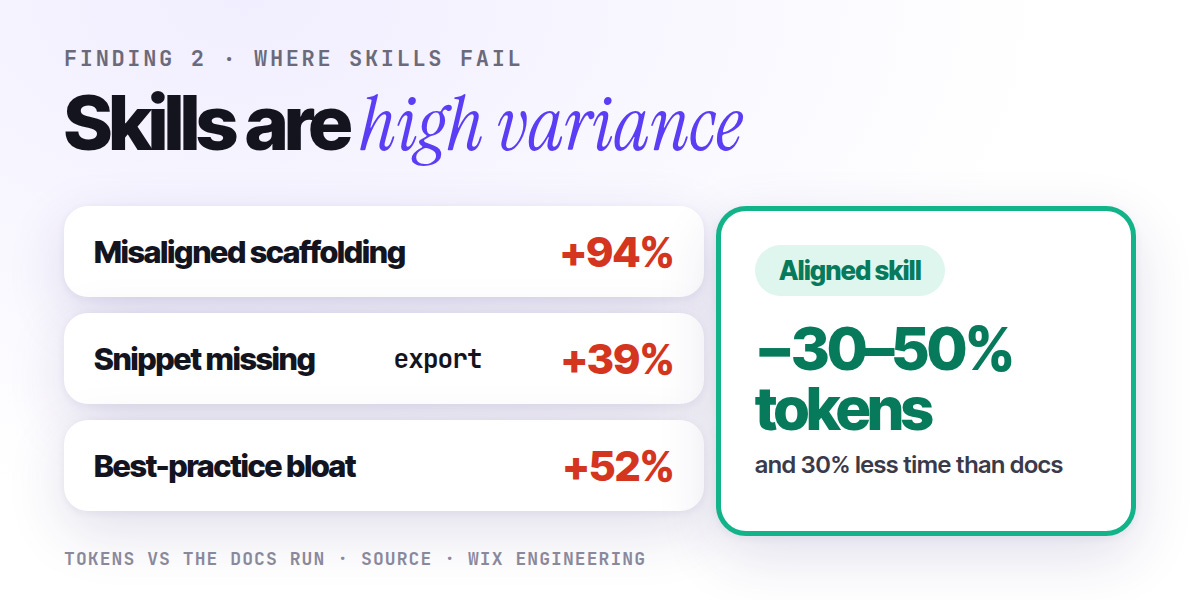
2. A slightly wrong skill is expensive. Three small skill mistakes cost 94%, 39% and 52% more tokens than the docs run. A well-aligned skill saved 30–50%. Skills are high variance.
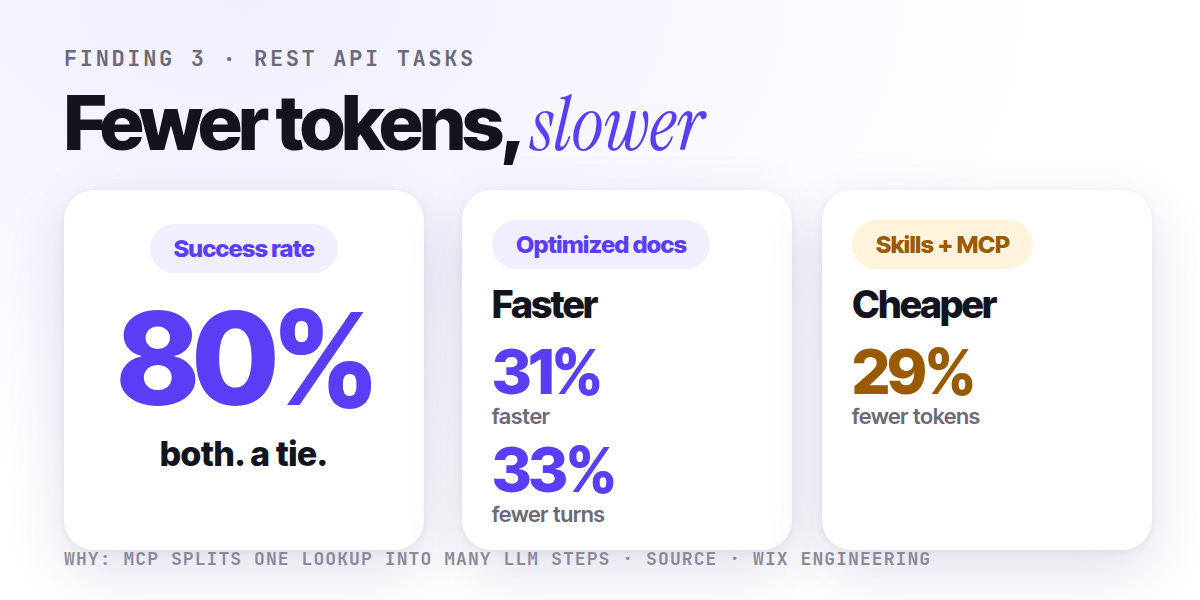
3. Fewer tokens can mean slower. On REST tasks both hit 80% success. Docs were 31% faster; skills used 29% fewer tokens. MCP splits one lookup into several calls, and each call is another LLM step.
4. Skills can make agents less curious. Anchored to a skill, agents skipped simpler routes that docs-only agents found.
The model to steal
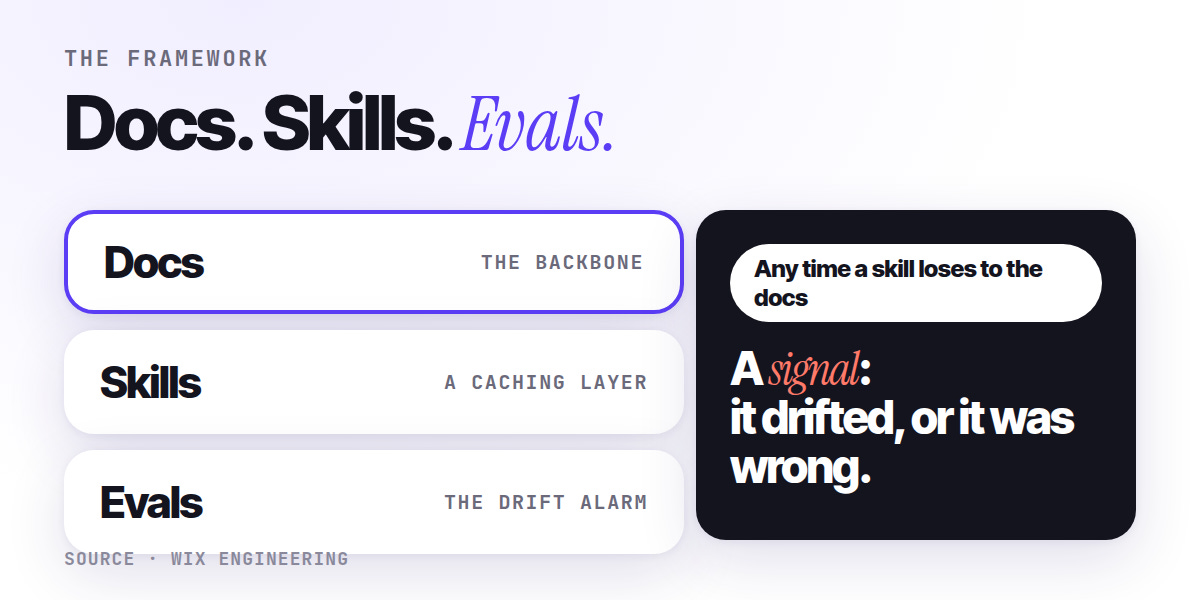
Docs are the backbone. Skills are a cache. Evals are the drift alarm: any time a skill loses to the docs, something drifted or it was wrong from the start.
Framework: docs backbone, skills caching layer, evals drift alarm
Do this week (a few hours)
Pick 5–10 real tasks. Run each under three conditions: current docs, improved docs, your skills. Three runs each. Track completion, tokens, turns and wall-clock time, not just pass rate. Treat any skill that loses to the docs as a bug, and read the failed runs. The aggregate score tells you something is wrong; the failed runs tell you what.
Caveat: the agents graded themselves and each task ran three times, so read the numbers as directional.
▶ Watch the 9-minute breakdown:
📄 Read the original post: We Ran 250 AI Agent Evals to Find Out if Skills Beat Docs (Wix Engineering, Adam Friedmann)
Next week: how a bigger VM can change a benchmark score.
Hit reply with one answer: which skill have you never checked against your docs?